Pi Context Optimization Platform
Configured under-64K working context engine with cache prefix stabilization for engineering teams running AI via subscriptions (Claude Pro/Max, ChatGPT Team) and continuous agentic workflows.
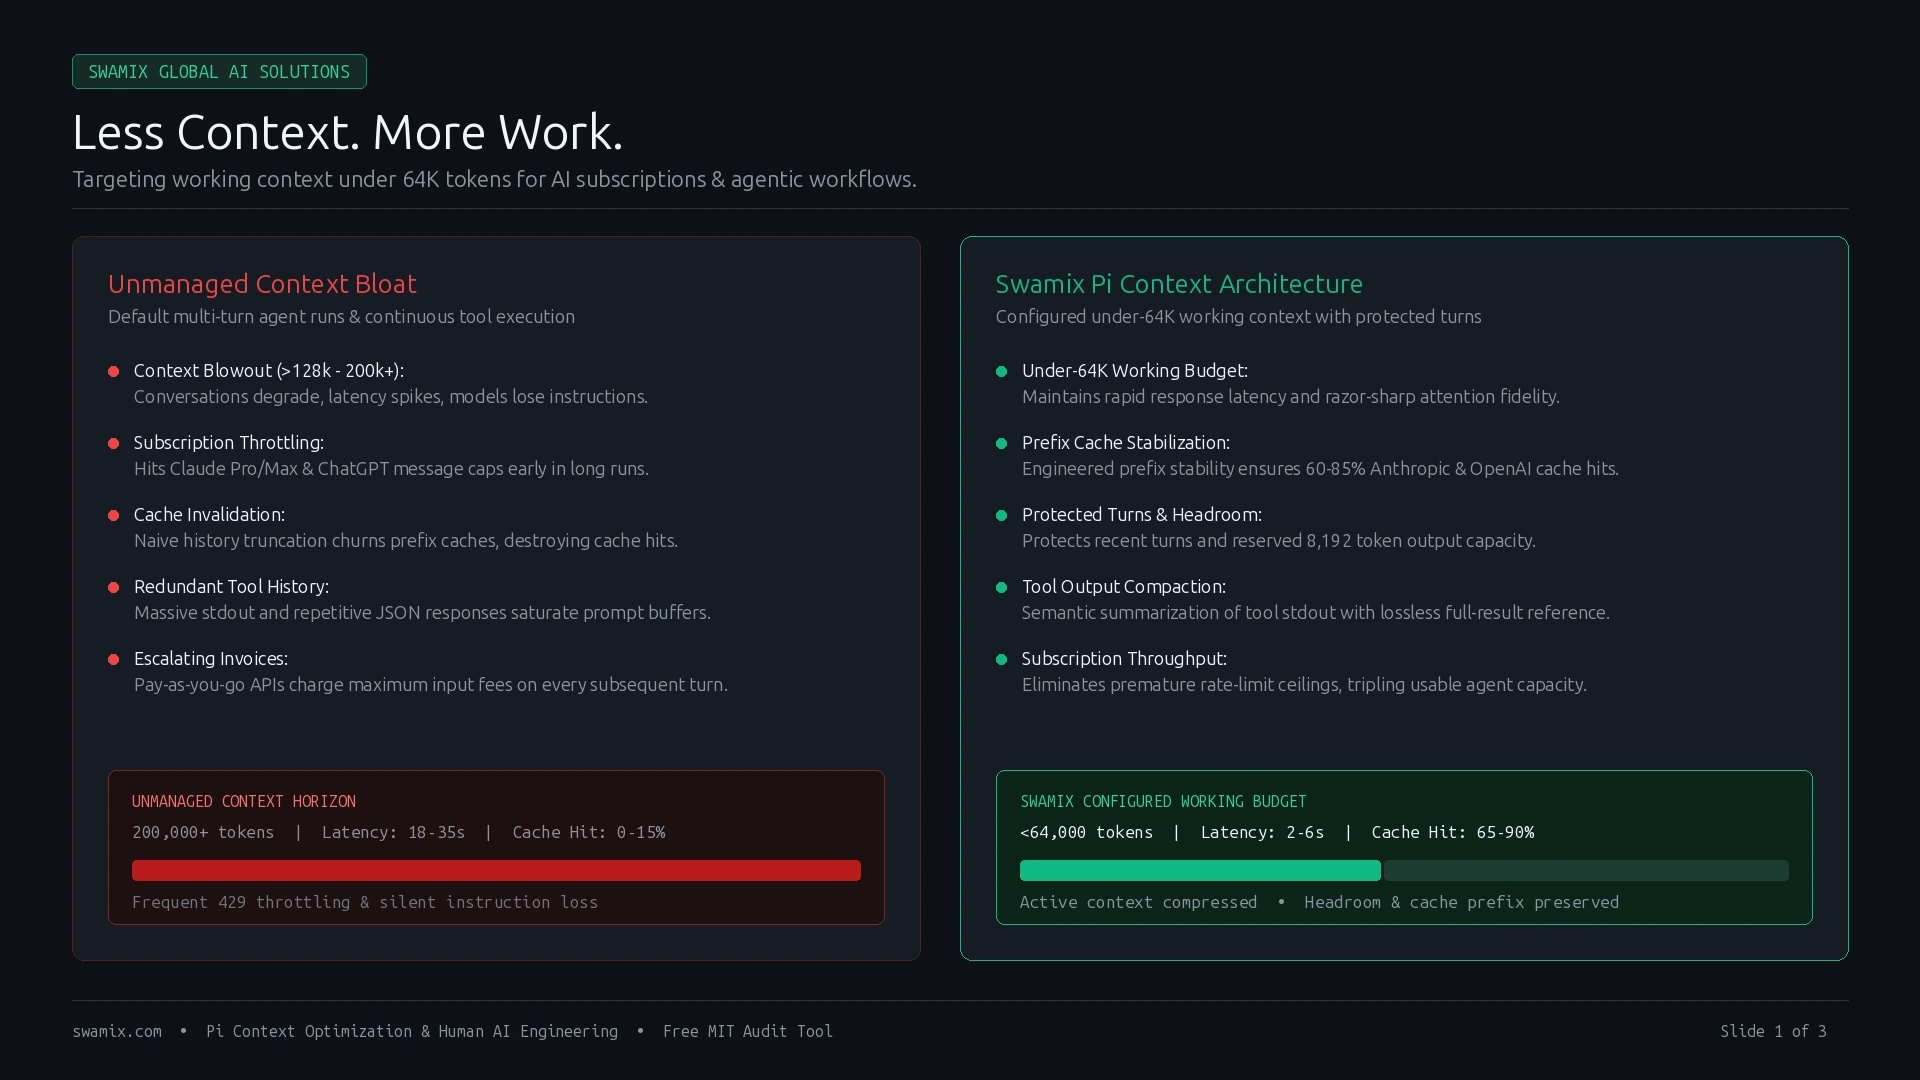
Context Compression & Working Horizon
Comparing unmanaged 200k+ context bloat with Swamix's under-64K configured architecture
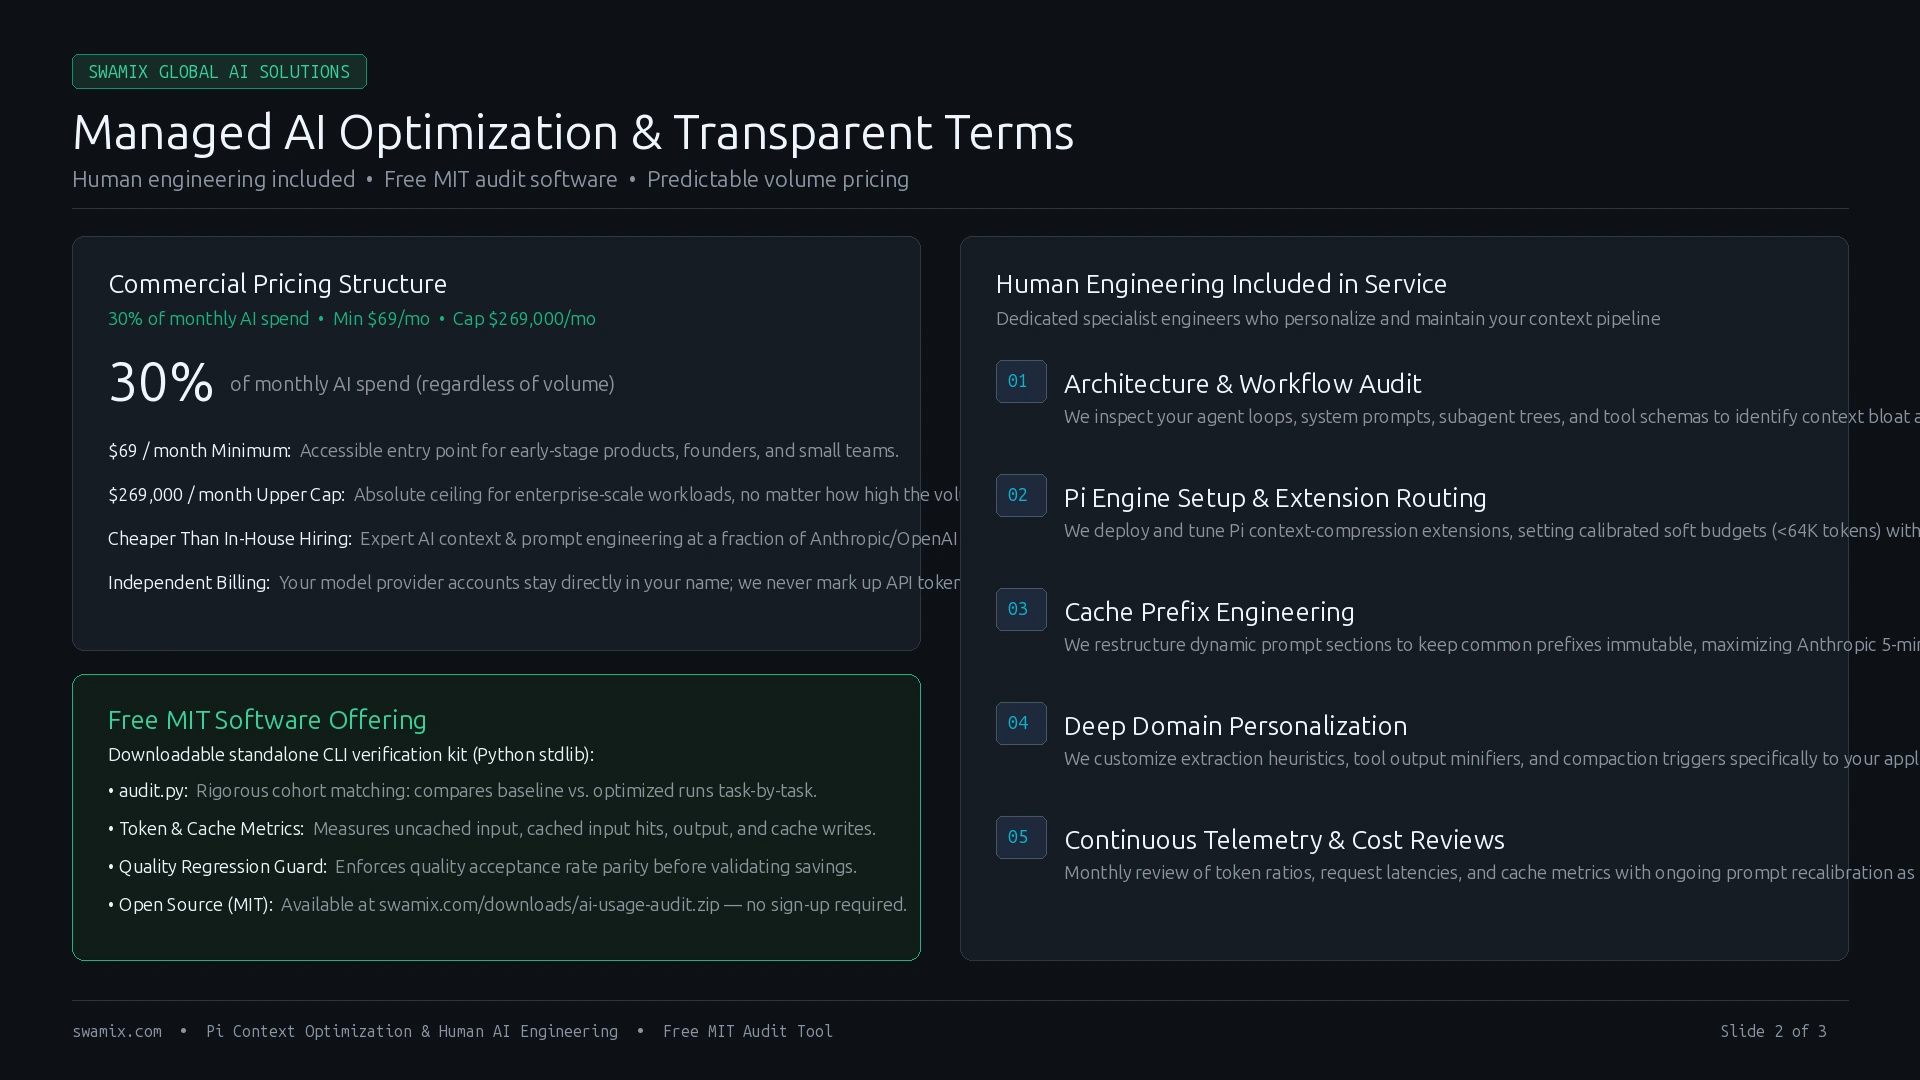
Human Engineering Included & Transparent Terms
We provide dedicated engineers for setup, cache prefix tuning, domain personalization, and ongoing telemetry
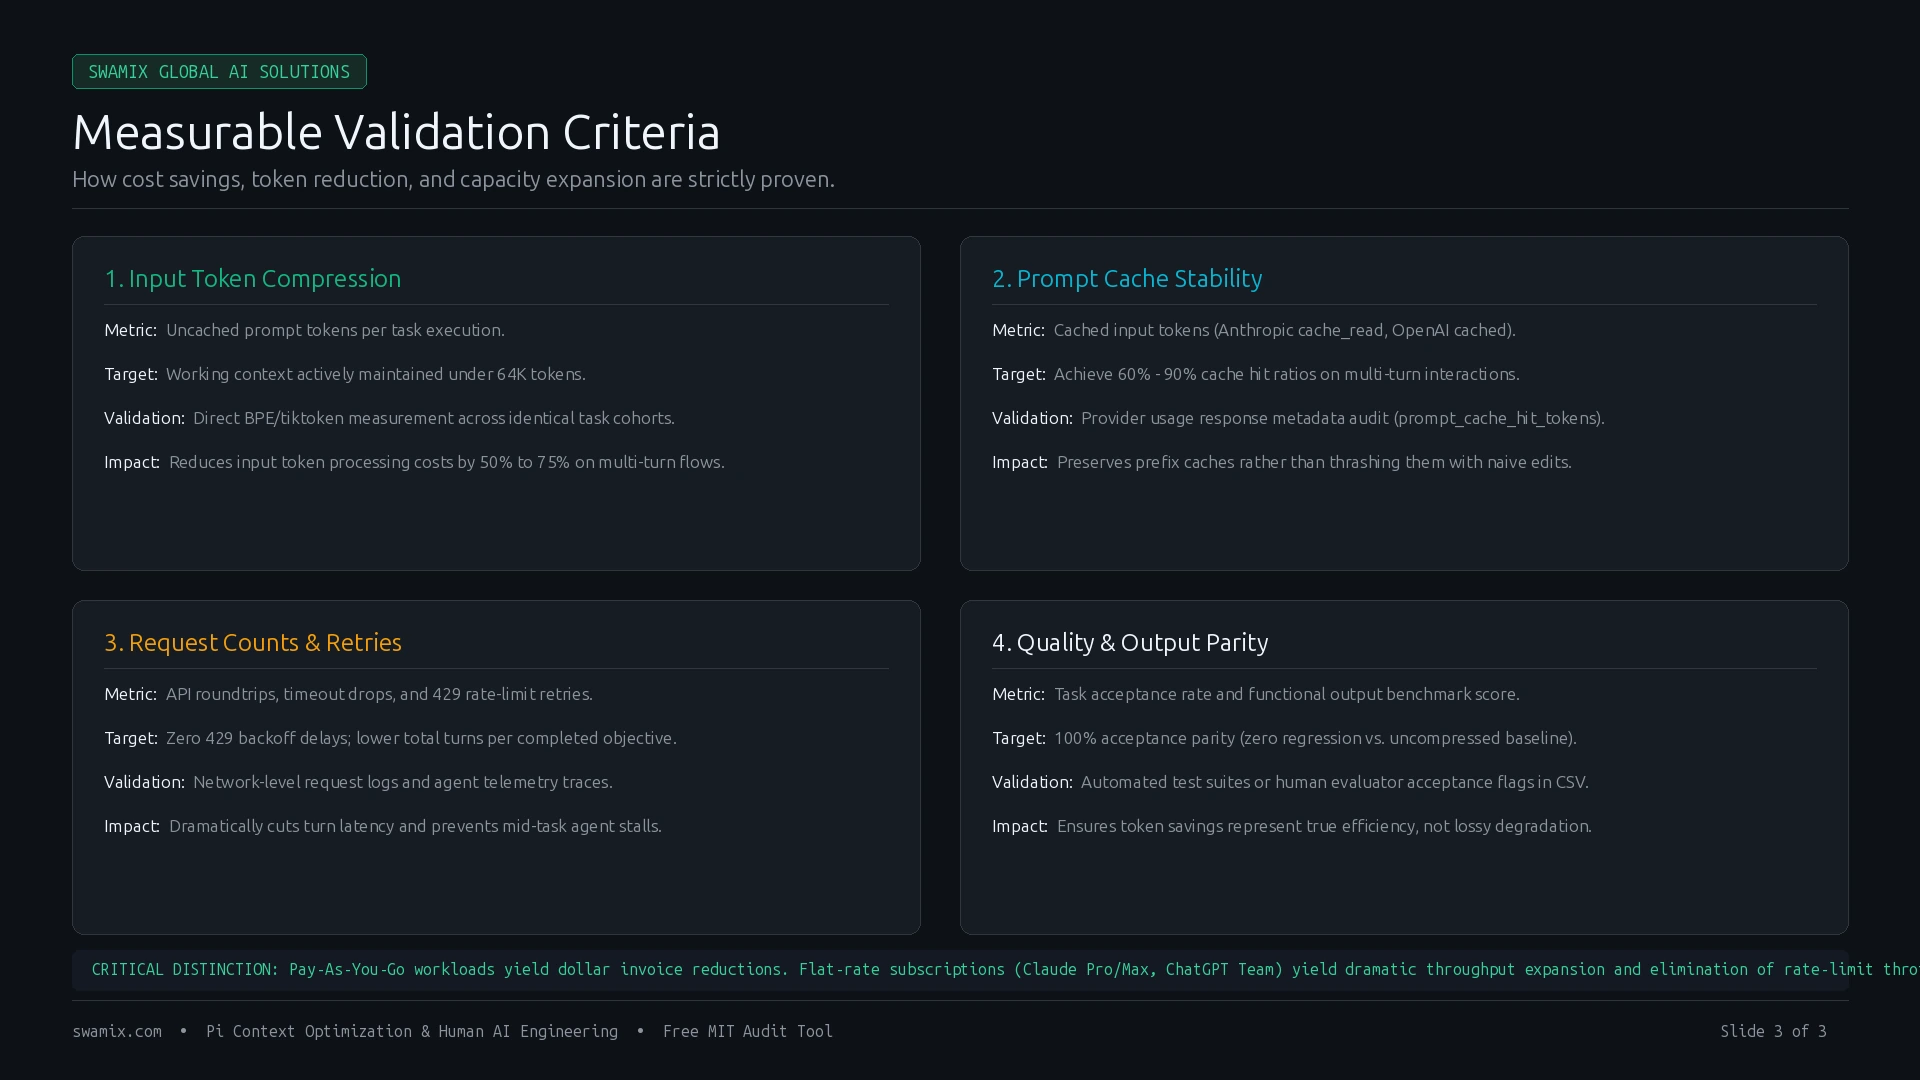
Measurable Validation Criteria
Strict measurement criteria: token reduction, cache hit verification, request counts, and quality acceptance
Under-64K Technical Specifications
Prefix Cache Stabilization
Dynamic history modifications invalidate Anthropic's 5-minute and OpenAI's prefix cache. Our engine strictly preserves identical system prompt and schema prefixes so subsequent turns hit provider prompt cache (60–90% hit rates).
Semantic Tool Compaction
Large tool results (Bash logs, AST dumps, SQL returns) are compactly summarized into high-signal key facts while maintaining a read-only disk reference to full output, keeping agent prompt buffers clean.
Protected Turns & Headroom
The newest two conversation turns and active tool calls are strictly protected from compaction. An 8,192 token output capacity is reserved, ensuring models never hit generation truncation walls.